Local AI4 min read
Meaning Search, on your machine
Find a clip by the idea you remember. A practical guide to exact search, local embeddings, and Ollama setup.
By ClipsX
The frustration of the tip-of-the-tongue search
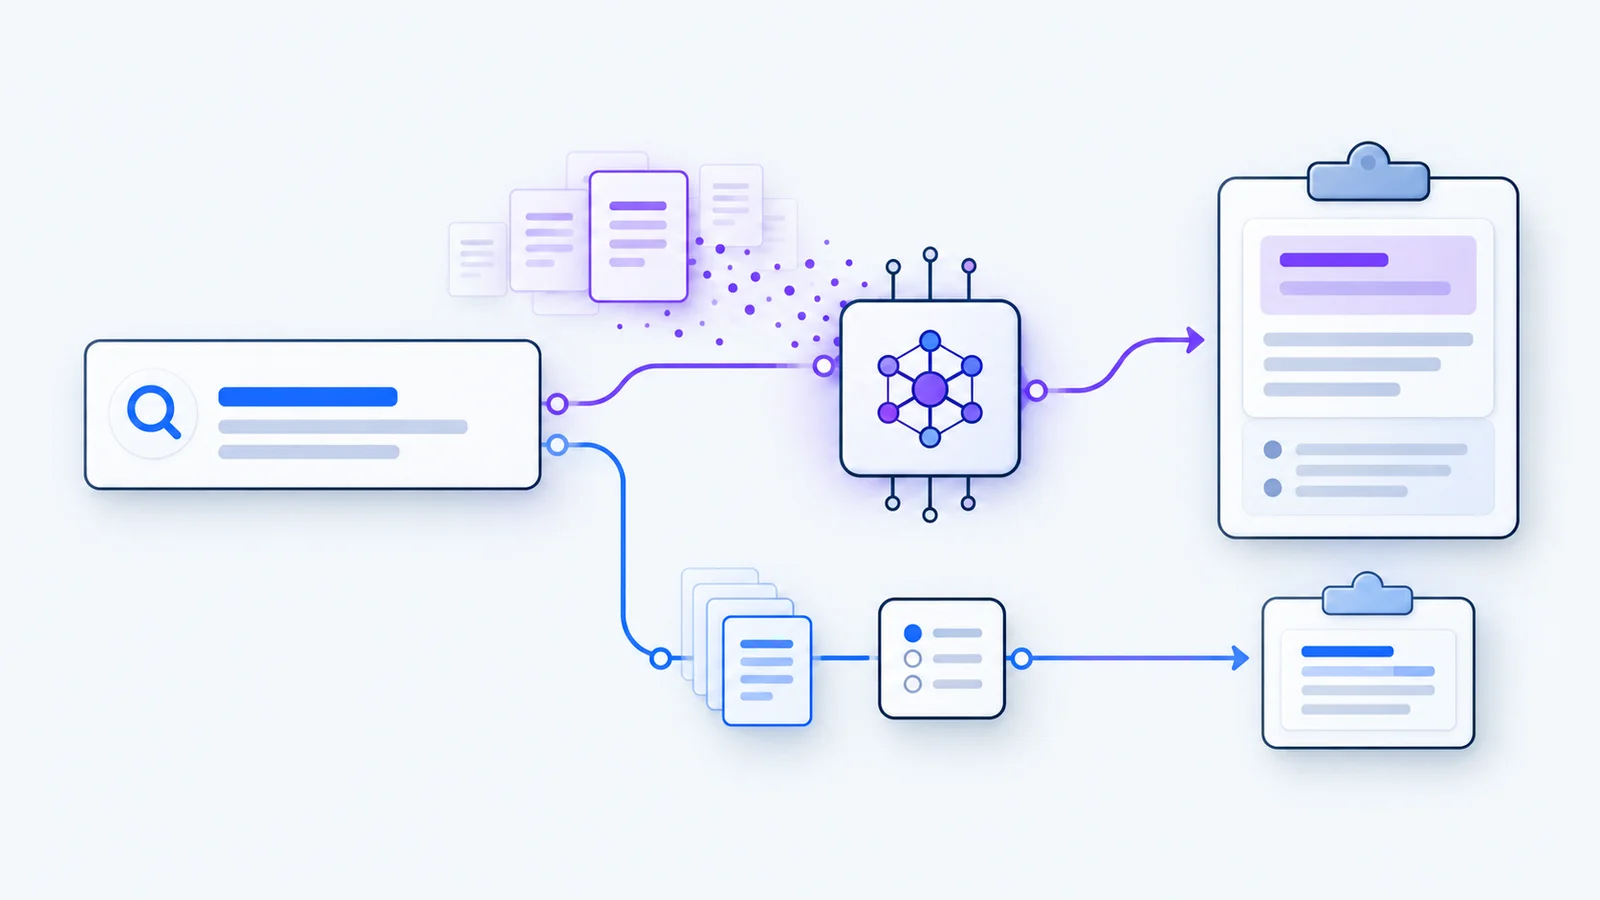
Every developer and knowledge worker knows the feeling. You copied a multi-line Docker command three weeks ago to clean up hung containers and dangling volumes. Today, you urgently need it, but you search for “clean up docker space”. The original clip contained docker system prune with specific flags. Not a single keyword matches. Standard exact-string search returns nothing, and you end up scouring the web all over again.
Exact keyword search is unbeatable for unique strings—error codes, UUIDs, function names like handleWebhookCallback, or configuration keys. But human recall is conceptual: we remember what something did, not the exact phrasing we copied. ClipsX combines keyword and semantic retrieval in a unified engine, allowing you to find clips by verbatim syntax or by remembered intent without juggling separate tools.
Dense embeddings: search by concept, not keywords
An embedding model converts human language into high-dimensional vectors—numerical representations that capture semantic meaning. ClipsX indexes eligible clipboard text, manual notes, tags, and completed OCR extractions using local vectors. When you type a query, the model compares vector proximity. This allows “quiet spot to work” to match “café with fast Wi-Fi and power outlets”, even when zero words overlap.
Meaning Search is designed for retrieval, not speculative text generation. It returns your authentic saved clips and highlights matching excerpts. It is distinct from generative features like Recall, which synthesize new paragraphs from retrieved context. You can use semantic search without configuring text generation, ensuring that you always inspect the original, unaltered snippet before executing commands or sharing code.
Running local embeddings with Ollama
Ollama provides a lightweight local runtime for machine learning models. Unlike resource-heavy generative models that require gigabytes of VRAM, embedding models (such as nomic-embed-text or bge-m3) are compact, fast, and run effortlessly on consumer laptops. ClipsX connects to Ollama over a standard local loopback interface, ensuring that zero clipboard text leaves your machine.
- Install and start Ollama, then pull a specialized embedding model such as ollama pull nomic-embed-text.
- In ClipsX, navigate to Intelligence → Models, enter your local endpoint (http://localhost:11434), and select Connect.
- Choose your installed embedding model and toggle on Meaning Search.
- Allow the local background indexer to process eligible clips, then test a conceptual query to inspect matching passages.
Local intelligence with zero cloud telemetry
Embedding models take up negligible disk space (typically 200MB to 600MB), and inference takes only milliseconds per query. However, initial indexing of a massive historical backlog consumes CPU cycles and temporary compute. Start with a lightweight model optimized for your primary languages. Massive models rarely improve retrieval accuracy for short snippets and only increase indexing duration.
Using the loopback http://localhost:11434 connection guarantees on-device inference. Fetching the initial model weights requires an internet connection, and Ollama also supports remote hosting configurations. Never assume that the label AI automatically implies offline safety. Verify your model endpoint and network activity to confirm that your clipboard vectors remain strictly on local storage.
Diagnosing missing results and tuning thresholds
If Ollama stops running, ClipsX gracefully falls back to instant keyword search. Check that the Ollama service is active and that your chosen embedding model is still available. If recent clips are missing from semantic queries, check the background indexing queue. OCR-derived text becomes searchable only after local image character extraction completes.
Vector similarity represents distance in mathematical embedding space, not guaranteed factual correctness. An optional minimum similarity threshold filters out weak semantic candidates without affecting exact keyword matches. Setting this threshold too high can obscure useful related clips; adjust it thoughtfully using real-world query examples from your daily notes.
Your clips are permanent; indexes are disposable
Changing your embedding model in ClipsX automatically creates a replacement index alongside the active one, ensuring uninterrupted search. An explicit Reindex All command clears and rebuilds text vectors from scratch. In all cases, your original clipboard history remains completely untouched. You can disable Meaning Search at any moment to return to pure, instant keyword search without any model dependency.
Sources & next steps
Keep exploring
All articles
Assistant workflows4 min read
Let your assistant find what you already copied
Connect Claude Code, Codex, or any MCP client to your clipboard. Turn copied snippets into grounded engineering handoffs, coding context, and research briefs.
Read article
Extensions4 min read
Why clipboard extensions need boundaries
You copy API tokens, customer records, and private messages every day. Here is how WebAssembly sandboxing lets you format and transform snippets without leaking your clipboard.
Read article
Privacy4 min read
Local-first is a data boundary, not a badge
What stays on your device, what an optional account changes, and what to check before connecting a service.
Read article